While compiling the full openEHR CKM archetype set (from the CKM mirror repo), I noticed that 17 archetypes have SLOTs constrained to openEHR-EHR-CLUSTER.multimedia (.v0/.v1), but no archetype with that ID exists anywhere in the CKM.
3 of the referring archetypes are published/mature (v1):
The remaining 14 are v0 archetypes (e.g. CLUSTER.dwelling.v0, CLUSTER.exam_faeces.v0, the inspection_body_fluid family, OBSERVATION.audiogram_result.v0, OBSERVATION.hearing_screening_result.v0, INSTRUCTION.informed_consent_request.v0, …).
What the CKM does have is openEHR-EHR-CLUSTER.media_file.v1.
So my questions:
Why can’t CLUSTER.multimedia be found in the CKM — was it a draft that got renamed/superseded before publication?
Is CLUSTER.media_file.v1 the intended replacement? If so, is it safe/correct for tooling to resolve those multimedia SLOTs to media_file.v1, or should the referring archetypes eventually be revised to update their SLOT constraints?
Is there any successor for CLUSTER.multimedia_source.v0, or is that one fully retired?
@heather.leslie@ian.mcnicoll - tagging you since you authored these. Any pointers to the history/rationale would be much appreciated.
The vast majority of slot constraints are essentially recommendations, not fixed requirements, so you are perfectly at liberty to use CLUSTER.media_file.v1. We only make the slot-filler archetypes fixed in rare circumstances.
Having said that, these published archetypes should have the constraints updated
Social summary (Clinical Knowledge Manager) is little more than a detail slot. None of the included cluster archetypes seems to exist in the ckm. It is published as well, probably the worst offender in this regard…
In many cases only v0 exists, but include refers to v0 and v1 such as:
openEHR-EHR-CLUSTER.laboratory_test_panel.v1 included in openEHR-EHR-OBSERVATION.laboratory_test_result.v1 does not exist.
Two slots in openEHR-EHR-EVALUATION.tobacco_smoking_summary.v2
The blood pressure archetype refers to openEHR-EHR-CLUSTER.level_of_exertion.v1 while only v0 exists, in this case v0 is not included.
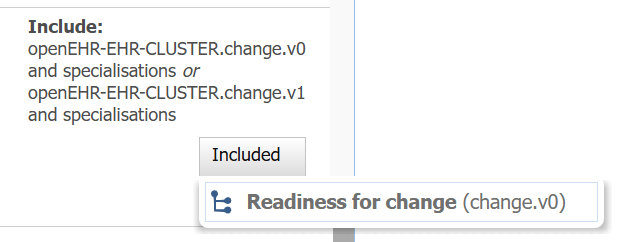
I believe I had other cases where the archetypes just didn’t exist at all, but I don’t remember which ones it was. I definitely got used to checking for it. If a slot includes clusters but does not have the included button, thos clusters do not exist. I always click on the button, this will reveal the list of included archetypes that are actually in the ckm.
You can also use the overall validation report (from the Reports menu) and filter by WRANF to see all of these warning for all archetypes.
As Ian has said, these are only recommendations, and other archetypes are allowed unless explicitly excluded. Some of them may be placeholders for archetypes yet to be defined.
Hi there. I went through all public archetypes available in the international CKM and created a spreadsheet with all archetypes that contain an inclusion or exclusion statement with a regex that does not point to an existing/public archetype in the international CKM. This might be useful to hunt down all invalid inclusion/exclusion statements.
Oh wow. This gives me an idea.. I don’t know what @sebastian.garde will think
Can I point an AI to the CKM to make these kind of easy changes by themselves?
Think dependabot, but with clinical model linting.
I do know the existence of the CKM REST API docs - Swagger UI, but is it built for these kind of use cases?
This would need to go through IEB / CPB but I can absolutely see the value of supporting a moderately knowledgeable editor to quickly ‘ok’ the changes and have them automatically uploaded as patch changes into CKM - that would be fantastic.
What we want to add to the spreadsheet, is an attempt at identifying the ‘correct’ slot-fillers (if appropriate) -maybe @sebastian.iancu MCP server can help with that.
@Martin - it would also be really helpful to add in the Slot atCode and Slot descriptionand perhaps the full slot constraint (the latter just for orientation i.e what were the other slot-fills?)
Hi @ian.mcnicoll ,
On CPB we have a spreadsheet of archetypes that need to be fixed and all changes requests appointed to each one (it includes the list you mentioned @Martin_Koch). We use the CKM api to get these. Last year we were working on a decision table of what can be considered as a quick fix and hopefully start by those. We are starting some working groups with collaborators to aid on this (e.g. translations wg, documentation/tutorials) and also having collaboration from the future appointed clinical modeller to address some of the cases.
If members of the community do know how to make a “quick” fix of the archetype and are able to provide a new version by upload it to the ckm ( @Sidharth_Ramesh the process you exposed is correct) that would save us a lot of time and we are greatly appreciative of this, as currently, all the work is done voluntarily when CKA’s and reviewers have available time.
Although I believe we are making progress, we still have a way to go as we are defining processes and that takes some time. Even posting here on discourse what are the current issues the community is having, helps us identify the most needed cases.
Cool - but I think @Sidharth_Ramesh was being even more ambitious - allow these slot constraints to be corrected by LLM (after human review) and automatically uploaded and merged without further human activity. There are definitely governance/ safety considerations but slot-fil mismatches does feel like a pretty low-risk place to investigate the possibilities.
You can edit the translations - and also the original language - directly in CKM. This has been the sweet spot.
You cannot, however, edit the structure of an archetype as such. We could develop such a thing, but given there are editing tools out there that focus on that, I am not sure if it time well spent. The general separation between the governance of the models (in CKM) and their editing in e.g. AD or whatever tool you like best has been a good principle I think. (Even though it occasionally reveals some differences in understanding of the specs, but resolving those things is helpful too…)
The slots across archetypes could benefit from some mass-editing/mass-correction either directly in CKM or by an external tool, be it AD, a simple text editor supporting regexes or maybe just text replacements, or some sophisticated AI helping you or the CKAs and editors.
How to get such changes - however they were made - back into CKM is a separate topic that probably requires a bit of discussion.
We could enable creation of Change Requests via the API or submission to a branch of yours for CKAs and editors to pick up.
But with that alone, in some ways we are just moving the bottleneck a bit - as all in all making the change per archetype isn’t all that hard, as far as I know, editors have typically handled them when they tackle the archetype next.
So for making this faster, you’d probably need to work directly on the trunk with the appropriate rights, either via the API or via bulk upload to CKM. Both - API and bulk upload - you can actually do for non-published archetypes at present already and we could possible extend this further…but it shortcuts the typical development cycles - for good and for bad.
While these problems have accumulated over time due to a lack of resourcing, there are still not that many (as you can see either from Martin’s Excel report or directly from the Validation Report in CKM which you can also export as CSV if needed) that I am unsure how much editor’s time as the key bottleneck in my understanding you can save by this.
All that said - for now - if you have updates they can always be submitted as CRs with the archetype attached and can then be integrated directly from the CR after checking by the editors.
And that’s fine when archetypes are under active review/ development - the problem I see here is largely for those that are stable (for good or bad). And I think removing these little bottlenecks over time can add up. Even a small change like this does take a fair bit of time.
Identify who is responsible and has time to do the work, make the change request
Download the archetype, make the change, re-upload, go through the branch/ trunk process to commit
Multiply that a hundred times and it becomes a real disincentive to do anything, particularly as it is kinda low priority in the overall pressures.
And if we can get it working, it might well be a pattern that can be built on for other ‘simple’ fixes, with apologies to @Seref
I think you and I are saying the same thing here in the end: namely that that process we both describe is not removing the bottleneck, at least not for stable archetypes (I agree).
The rest are suggestions on how to “get it working”; trying to find the right balance between
providing a simple fix for a number of archetypes on the one hand and
proper but not overeager governance to ensure these changes get into CKM trunk archetypes on the other hand while also
Hi there again! Thanks for the clarification @vanessap. As I am already working on this, I am going to leave the updated spreadsheet as suggested by @ian.mcnicoll here. TRhe list includes al inclusion or exclusions in the publicly available archetypes of the international CKM. It might be of interest to some people to have this list.
But what next? I was a bit confused with the trunk / upload revision option that was available vs opening up a change request and uploading the archetype there.
Is there a guide for this somewhere?
And I think it’s fairly simple to run an agent on this via browser automation. Just need to spend some tokens on the whole login, upload archetype steps - but not too bad. Everything else is available via the REST API.
Essentially, an editor of the archetype process the CR and take it from there (e.g. put on a branch, potentially add other changes, commit to the trunk, republish as required…)
If you mean uploading to the trunk via the REST API: This is mainly for automation and would assume you have sufficient rights to the archetype, otherwise you cannot do this. Typically an archetype is worked on a branch until you are happy with it (for example: a new translation) and can then submitted to an editor of the archetype who will take it from there and commit it to the trunk and for example republish the archetype as a patch or whatever is appropriate.
When there is a dedicated change request to the archetype, it makes sense to create a CR and attach the archetype to it. This will reference the CR in log messages, editors have CR lists that they can work with etc. and the CR will be marked as completed once done. An editor can create a branch and for example integrate various CRs into it and commit that to the trunk.
We already have a card for adding CR creation to the REST API which will make this more straightforward.
Very much appreciated! Let me know when you release it.
So I’m currently building a bot that’ll function like Dependabot but on the CKM for Archetypes. If there’s a nightly scan on these sort of issues, is creating a CR the best option?
So, I’m assuming a CR still doesn’t fully remove this part that the contributor has to manually do in order to get the change incorporated? How much time does this part of the process take after the CR is raised? And would this kind of functionality be worth the time saved?
I would be great if authors can incorporate the CR raised without spending too much time. What’s so appealing about dependabot on Github is the ability for someone with merge with a single click if they think the changes are okay - no cloning the repo, and checking out the branch etc. It’s all done on the web UI.