# Usage of OID, URI (URL/URN) in DV\_IDENTIFIER fields?
**URL:** https://discourse.openehr.org/t/usage-of-oid-uri-url-urn-in-dv-identifier-fields/2508
**Category:** Specifications
**Created:** [8 April 2022 09:40 UTC](https://discourse.openehr.org/t/usage-of-oid-uri-url-urn-in-dv-identifier-fields/2508 "2022-04-08T09:40:00Z")
**Posts on this page:** 4
**Page:** 1
### Author:  [@erik.sundvall](https://discourse.openehr.org/u/erik.sundvall)
#### Post date: [8 April 2022 09:40 UTC](https://discourse.openehr.org/t/usage-of-oid-uri-url-urn-in-dv-identifier-fields/2508/1 "2022-04-08T09:40:00Z")
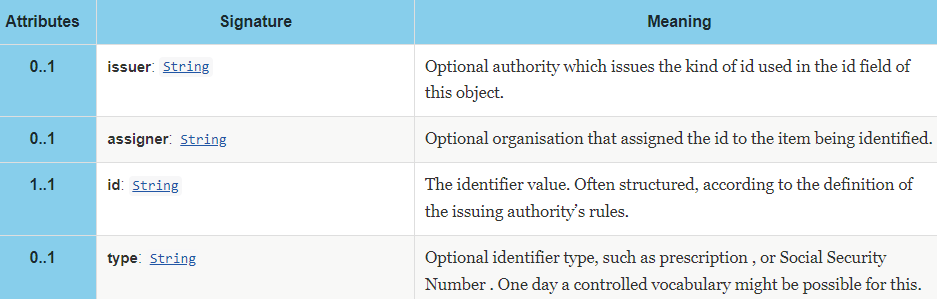
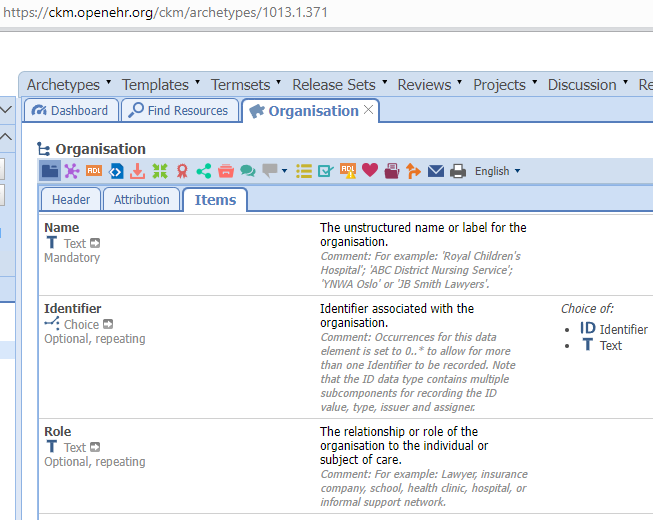
Sometimes we need to use URIs or OIDs as content for the `id` field of the [DV\_IDENTIFIER Class](https://specifications.openehr.org/releases/RM/latest/data_types.html#_dv_identifier_class) (e.g. in the [Organisation archetype](https://ckm.openehr.org/ckm/archetypes/1013.1.371)).
URIs are often kind of self-explanatory and may implicitly carry information about type/issuer/assigner. Most OIDs are also interpretable using lookup services.
Questions:
1. Is it reasonable to skip the type/issuer/assigner-attributes when putting self-explaining URIs in the `id ` field
2. When putting OIDs in the `id ` field for some use cases without the need for type/issuer/assigner-attributes, should we reccomend to prefix the OID with `urn:oid:`?
3. When putting an OID in the `type` field should we reccomend to prefix the OID with `urn:oid:` to make it clear that it is an oid?
Example of #1, a self assigned ID of a private organisation that does not have a Swedish HSA-ID for care:
- [DV\_IDENTIFIER.id](https://specifications.openehr.org/releases/RM/latest/data_types.html#_dv_identifier_class) = [http://id.yourplasticsurgeon.se/face-department](http://id.yourplasticsurgeon.se/face-department)
Example of #3 is a Swedish HSA-ID for care :
- [DV\_IDENTIFIER.type](https://specifications.openehr.org/releases/RM/latest/data_types.html#_dv_identifier_cla) = urn:oid:1.2.752.29.4.19 (an OID marker for swedish care unit HSA-IDs)
- [DV\_IDENTIFIER.id](https://specifications.openehr.org/releases/RM/latest/data_types.html#_dv_identifier_cla) = SE2321000016-150H (the HSA-ID for Täby Vårdcentral, a specific primary care center)
Table from specs:
---
### Author:  [@joostholslag](https://discourse.openehr.org/u/joostholslag)
#### Post date: [13 April 2022 15:41 UTC](https://discourse.openehr.org/t/usage-of-oid-uri-url-urn-in-dv-identifier-fields/2508/2 "2022-04-13T15:41:05Z")
> [@erik.sundvall](#):
>
> Is it reasonable to skip the type/issuer/assigner-attributes when putting self-explaining URIs in the `id ` field
Why would you skip it? It seems trivial to fill and could be very valuable, e.g. for a computer or human that doesn’t natively understand the implied metadata.
---
### Author:  [@erik.sundvall](https://discourse.openehr.org/u/erik.sundvall)
#### Post date: [13 April 2022 16:13 UTC](https://discourse.openehr.org/t/usage-of-oid-uri-url-urn-in-dv-identifier-fields/2508/3 "2022-04-13T16:13:07Z")
> [@joostholslag](#):
>
> Why would you skip it?
Mostly to reduce redundancy and space. In the Swedish use case I am thinking of these will be used in the “Identifier” field of the archetype “[Organisation](https://ckm.openehr.org/ckm/archetypes/1013.1.371)” and the “Role” will already be SNOMED-coded as 43741000|Care unit. A sImilar structure will be repeated twice for EVERY composition, thus we want to reduce redundant info.
I also added an example of #1 to my post above.
---
### Author:  [@pablo](https://discourse.openehr.org/u/pablo)
#### Post date: [17 April 2022 17:31 UTC](https://discourse.openehr.org/t/usage-of-oid-uri-url-urn-in-dv-identifier-fields/2508/4 "2022-04-17T17:31:47Z")
The issue with skipping those other fields because might be already coded in the id, is querying then needs to decode the id or query inside a string value, because the RM and AQL don’t know how to process the format. This implies that an implementation needs to decode the value first, to know the type, then process/query the value based on the type.
IMO it is way better to have all the redundancy to simplify processing and querying of data, and avoid any encoded data here, which implies a decode is needed.